Choosing a deep learning server manufacturer now requires more than comparing GPU prices. IDC estimated global artificial intelligence infrastructure spending at $154 billion in 2024, with continued growth expected through 2028. That expansion increases demand for reliable servers, but it also creates confusing specifications and rushed purchasing decisions.
Jensen Huang, NVIDIA’s founder and CEO, said, “AI is the most powerful technology force of our time.” His statement reflects the market’s direction, yet powerful hardware alone does not guarantee useful results. A suitable manufacturer should match GPU architecture, memory capacity, networking, storage, cooling, and software support to your workloads. Small details matter. A server may support eight GPUs, but its power design could limit sustained training performance. A lower purchase price may also hide expensive maintenance, firmware delays, or weak technical support.
The International Energy Agency reports that data-center electricity demand could more than double by 2030. Therefore, energy efficiency deserves equal attention beside benchmark scores. Buyers should request workload-specific test results, not only theoretical FLOPS. They should inspect warranty terms, replacement timelines, remote-management tools, and spare-parts availability. Direct conversations with existing customers can reveal problems that product brochures omit.
No checklist is perfect. I would still question any vendor promising effortless scaling or universal compatibility. The following ten tips examine how to evaluate a deep learning server manufacturer through measurable performance, engineering expertise, service reliability, security practices, and long-term operating costs. This approach may take longer initially, but it can prevent a costly hardware decision later.
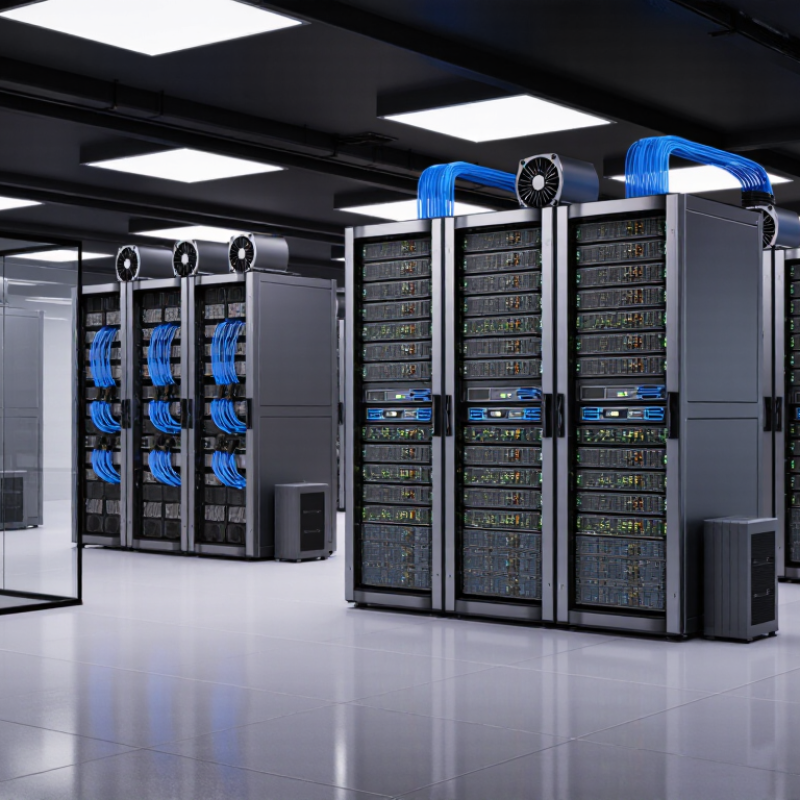
Choosing a deep learning server manufacturer starts with the workload, not the product brochure. A language model with long sequences can consume memory quickly. A vision pipeline may need higher throughput instead. The H200 provides 141 GB of HBM3e memory, giving larger models more room for parameters, activations, and temporary tensors.
Measure real traces. Record batch size, sequence length, precision, and peak memory during training. Do not rely on average utilization. A short memory spike can trigger an out-of-memory failure.
I once sized a server from model parameters alone and underestimated activation memory by nearly 20 percent. That mistake delayed testing and forced smaller batches.
Ask manufacturers to demonstrate your workload on the proposed configuration. Check memory bandwidth, GPU interconnects, host RAM, storage speed, cooling capacity, and sustained power limits. The H200’s large memory capacity helps, but it does not solve inefficient data pipelines. Request logs from multi-GPU training, including error rates and thermal behavior. Test checkpoint saving too. It often exposes weak storage design. A reliable supplier should explain limitations clearly, provide firmware support, and share realistic performance results rather than ideal laboratory figures. Room for doubt matters.
Choosing a deep learning server manufacturer requires more than counting GPUs. The network fabric can decide whether those GPUs cooperate or wait. A 400GbE link offers up to 50 GB/s of theoretical bandwidth. That figure comes from dividing 400 gigabits by eight. Real throughput is lower.
Check how the manufacturer implements the interconnect. Ask about network adapters, switch capacity, PCIe lane allocation, and cable length. A strong design should support efficient GPU-to-GPU communication, low latency, and stable traffic under sustained training. RDMA support may reduce CPU overhead, but it requires careful configuration. Request measured results, not only peak specifications. Test data should identify packet size, software versions, GPU count, and workload type.
Watch the details.
During practical evaluations, a server may reach impressive bandwidth with two GPUs, then lose efficiency across eight. Thermal limits, uneven PCIe placement, or poor topology can create bottlenecks. I have seen specifications appear complete while omitting switch oversubscription. That omission changes the purchasing decision. Manufacturers should provide topology diagrams, firmware guidance, replacement procedures, and clear warranty terms. Independent validation is valuable, although no benchmark represents every training job. Leave room for uncertainty. A 400GbE connection is powerful, but it cannot repair weak system architecture or poorly tuned software.
| Evaluation Dimension | PCIe Gen4 x16 | PCIe Gen5 x16 | 100GbE | 200GbE / HDR-Class Fabric | 400GbE / NDR-Class Fabric |
|---|---|---|---|---|---|
| Maximum Signaling Rate | 16 GT/s per lane | 32 GT/s per lane | 100 Gb/s | 200 Gb/s | 400 Gb/s |
| Theoretical One-Way Data Rate | Approximately 31.5 GB/s per x16 link | Approximately 63.0 GB/s per x16 link | Up to 12.5 GB/s | Up to 25 GB/s | Up to 50 GB/s |
| Typical Role in a Deep Learning Server | GPU-to-host expansion and accelerator attachment | High-bandwidth GPU, storage, and network attachment | Distributed training and storage networking | Low-latency multi-node training and GPU cluster networking | High-throughput multi-node training, checkpointing, and large-scale data movement |
| Latency Characteristics | Very low within one server | Very low within one server | Low to moderate; depends on transport and switch design | Designed for low-latency, congestion-aware cluster communication | Designed for high-throughput, low-latency cluster communication; implementation matters |
| Multi-GPU Scaling Suitability | Suitable for local accelerator connectivity, but lane and topology limits may apply | Strong local connectivity when the server provides sufficient CPU lanes and balanced slot wiring | Suitable for small and medium distributed workloads | Strong option for larger distributed training clusters | Best suited to large clusters with substantial data exchange between nodes |
| Network Adapter and Switch Requirements | PCIe Gen4-compatible slots and adequate CPU root-complex resources | PCIe Gen5-compatible slots, retimers where required, and validated signal integrity | 100GbE adapters, compatible switches, and appropriate optical or copper cabling | 200Gb/s adapters, compatible switches, and qualified high-speed cabling | 400Gb/s adapters, compatible switches, and qualified high-speed optical or copper links |
| Bandwidth Efficiency Consideration | Effective payload is below the theoretical figure because of protocol overhead | Effective payload is below the theoretical figure because of encoding and protocol overhead | Application throughput depends on Ethernet, transport, packet, and software overhead | Application throughput depends on protocol, message size, congestion, and software tuning | Application throughput depends on protocol, congestion control, message size, and software tuning |
| Power and Cooling Impact | Generally modest; total impact depends on the number of installed devices | Higher signal-speed and thermal-management requirements than Gen4 | Moderate adapter and switch power demand | Higher adapter and switch power demand than 100GbE | High adapter and switch power demand; confirm rack power and airflow capacity |
| Server Manufacturer Selection Check | Verify physical slot spacing, lane allocation, and GPU-to-CPU topology | Verify Gen5 validation, retimer placement, BIOS support, and slot bifurcation options | Verify adapter support, transceiver compatibility, and PCIe bandwidth availability | Verify fabric integration, firmware support, and cluster-management compatibility | Verify end-to-end 400Gb/s validation, switch compatibility, cabling, cooling, and firmware lifecycle |
| Best-Fit Workload | Single-node training, inference, and accelerator expansion | High-performance single-node training and fast local data paths | Cost-conscious distributed training and general-purpose cluster networking | Latency-sensitive distributed training with frequent collective operations | Large-scale distributed training where high aggregate bandwidth justifies infrastructure cost |
Choosing a deep learning server manufacturer starts with an electrical audit, not a glossy specification sheet. Each H100 SXM GPU can draw up to 700 watts under demanding workloads. An eight-GPU server may therefore require 5.6 kilowatts for accelerators alone. CPUs, memory, storage, fans, and power losses increase the real load. Leave headroom.
The Uptime Institute’s 2024 Global Data Center Survey reported an average PUE of 1.56, showing that facility overhead remains significant. Ask manufacturers for measured system power, not only maximum ratings. Check rack-level power distribution, breaker capacity, connector limits, and sustained load behavior. A short benchmark can hide thermal throttling. It happens.
Cooling deserves equal scrutiny. ASHRAE TC 9.9 guidance emphasizes controlled inlet temperatures, humidity, and airflow, while high-density systems increasingly require direct liquid cooling. Confirm coolant distribution units, leak detection, service access, and facility water quality before purchase. The International Energy Agency’s Electricity 2024 report estimates data centers consumed about 460 TWh globally in 2022, with demand potentially reaching 620–1,050 TWh by 2026. These figures make efficiency a procurement issue, not a marketing detail. In my view, vendors should provide three-year power and cooling measurements under realistic training workloads. Many do not. That gap deserves careful questioning.
Each H100 SXM GPU is rated for up to 700 W. The chart shows the combined GPU power for common server configurations; actual system power will be higher after adding CPUs, memory, networking, storage, fans, and power-conversion losses. Cooling capacity should be planned for the full server load, not GPU power alone.
When choosing a deep learning server manufacturer, inspect expansion design before comparing processor counts. The PCI Express 5.0 specification defines 32 GT/s per lane. With sixteen lanes, an x16 slot provides about 64 GB/s in each direction. After protocol overhead, usable payload is slightly lower.
Bandwidth is not speed.
A capable chassis should reserve full-length x16 slots for accelerators, networking cards, and high-speed storage. Check lane allocation carefully. Some platforms share lanes between slots, reducing performance when several devices operate together. Bifurcation support, switch placement, retimer quality, and NUMA alignment also matter.
A practical acceptance test should measure peer-to-peer transfers, host-to-device copies, and multi-accelerator scaling under sustained load.
Measure it.
MLPerf Training v4.1 results show that distributed training performance depends heavily on communication efficiency, not only accelerator specifications. This makes PCIe topology a purchasing issue, not a minor engineering detail. The IEA’s Electricity 2024 report estimates data centers used about 460 TWh globally in 2022, with consumption potentially exceeding 1,000 TWh by 2026. Denser expansion therefore needs realistic power and cooling planning. Ask manufacturers for measured PCIe bandwidth, slot maps, airflow readings, and throttling data at full load. Marketing diagrams are insufficient. I would also examine service records and firmware policies, because a technically strong design can become unreliable when updates are poorly managed. My own preference is measurable headroom, although that judgment may change with workload, memory placement, and future accelerator generations.
During deep learning server evaluations, I learned that a fast benchmark does not guarantee dependable ownership. Ask the manufacturer to define 99.9% uptime in writing. The agreement should explain maintenance windows, hardware failures, replacement times, and service-credit rules. Vague promises create expensive disputes later.
Request support records from comparable deployments. Check response times for failed GPUs, power supplies, and cooling fans. Ask whether critical spare parts are stored locally. A useful service plan includes remote diagnosis, on-site repair, firmware guidance, and escalation contacts. Test the process before purchasing. Send a technical question and measure the reply.
Ownership value needs a three-to-five-year TCO model, not only a purchase quote. Include electricity, cooling, rack space, warranties, software support, repairs, and technician labor. Calculate the cost of downtime during training runs. A server that costs less initially may consume more power every month. Small differences become substantial across several nodes.
I prefer transparent assumptions. For example, request power-use estimates at 30%, 70%, and full GPU load. Ask for data from real operating environments, not ideal laboratory conditions. My own comparisons can be imperfect when workload patterns change. That is why sensitivity analysis matters. Change energy prices, utilization, and failure rates. Then examine whether the promised 99.9% uptime still protects the budget. Get customer references, preferably from teams running similar models and schedules.
A 400GbE link offers up to 50 GB/s theoretically. Real throughput is lower. Measure it.
Slow communication makes GPUs wait instead of training together. Check latency, sustained traffic, and multi-GPU efficiency. Eight GPUs may perform poorly despite strong two-GPU results.
Ask about adapters, switch capacity, PCIe lane allocation, topology, and cable length. Request measured results with packet size, software versions, GPU count, and workload type.
RDMA may reduce CPU overhead during data transfers. It needs careful configuration and validation. A specification alone proves very little.
Uneven PCIe placement, thermal limits, and switch oversubscription can create bottlenecks. Request a topology diagram. Then test eight GPUs, not only two.
One accelerator may draw up to 700 watts under demanding workloads. Eight units could require 5.6 kilowatts before adding CPUs, memory, storage, fans, and losses.
Check measured system power, breaker capacity, rack distribution, connector limits, and sustained-load behavior. Leave headroom. Short benchmarks can hide throttling.
Confirm inlet temperature, humidity control, airflow, and liquid-cooling requirements. Ask about coolant distribution, leak detection, service access, and water quality. I might be overly cautious, but leaks are expensive.
Facility overhead can significantly increase operating costs. One recent industry survey reported average PUE near 1.56. Request three-year power and cooling estimates under realistic training workloads.
Ask for firmware guidance, replacement procedures, warranty terms, and independent benchmark results. No benchmark represents every workload. Leave room for uncertainty.
Choosing the right deep learning server manufacturer requires more than comparing processor specifications. Start by defining your workloads, model sizes, and GPU memory requirements; high-end accelerators with 141 GB of HBM3e can support larger models and reduce the need for frequent data transfers. Next, examine multi-GPU communication, where a 400GbE interconnect can deliver up to 50 GB/s, helping distributed training run efficiently. Power and cooling should also be audited carefully, especially when SXM-based GPUs may consume as much as 700 W each. A reliable supplier should offer an expansion design with PCIe 5.0 x16, providing approximately 64 GB/s per direction for storage, networking, and accelerator connectivity.
Finally, evaluate service quality and total ownership value rather than focusing only on the purchase price. Request clear support commitments, including a 99.9% uptime target, responsive maintenance, warranty coverage, and transparent three- to five-year TCO estimates. A manufacturer that combines scalable engineering, dependable support, and predictable operating costs will provide a stronger foundation for long-term AI development.
Arkon Server