Choosing an H100 server manufacturer is not simply a matter of comparing prices. The decision affects model training speed, uptime, energy use, and long-term operating costs. A serious buyer should examine the complete platform, not only the GPU label.
In real deployments, small details become expensive problems. Check whether the manufacturer provides genuine NVIDIA H100 GPUs, validated PCIe or SXM configurations, and adequate NVLink support. Inspect the cooling design, power distribution, rack density, and firmware process. An H100 server can draw substantial power, so a weak thermal plan may reduce performance or trigger downtime. Ask for independent benchmark results under sustained workloads, not short promotional tests. Also review warranty terms, replacement procedures, spare-part availability, and technical response times. These details matter when a training cluster stops at midnight.
Jensen Huang, NVIDIA’s founder and CEO, has often described the direction of computing plainly: “The future of computing is accelerated computing.” That view explains why the H100 remains important, but it does not make every H100 server manufacturer equally reliable. A capable supplier should understand CUDA environments, multi-GPU communication, storage bottlenecks, and data-center integration. Request clear documentation. Request references, too.
No checklist is perfect. Real workloads can behave differently from laboratory benchmarks. A lower-cost system may look attractive today, yet consume more power or require slower support tomorrow. The right manufacturer balances verified hardware, engineering discipline, transparent service, and practical deployment experience. This guide examines those factors before a purchase becomes an expensive lesson.
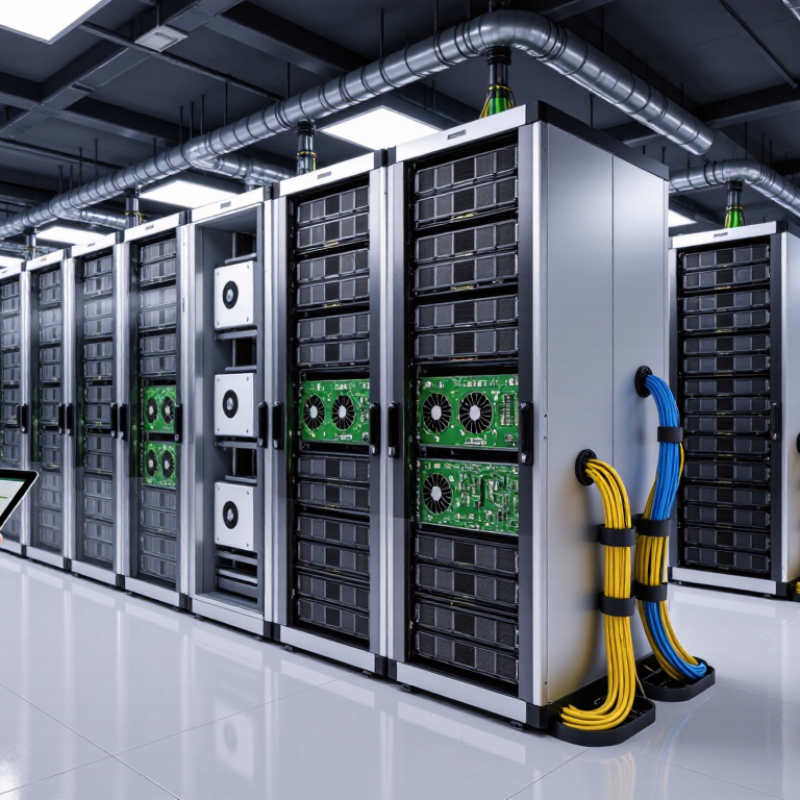
Define H100 Server Requirements: 80GB HBM3, 3.35TB/s Bandwidth, and 700W TDP
How to Choose an H100 Server Manufacturer?
Before comparing manufacturers, define the exact H100 server profile your workload requires. Specify 80GB HBM3 memory, 3.35TB/s memory bandwidth, and a 700W TDP target. These figures affect model selection, chassis design, power delivery, and cooling capacity.
Ask for a complete technical sheet, not a sales summary. Confirm the installed accelerator version, memory type, interconnect layout, CPU pairing, and PCIe generation. A reliable manufacturer should explain sustained performance under long training runs, not only peak specifications.
Request thermal test results at realistic ambient temperatures. Check whether the system can maintain stable clock speeds without excessive fan noise or throttling.
Power planning deserves careful attention. A 700W accelerator can expose weak power supplies, limited circuits, or poorly designed airflow. Require redundant power options, suitable rack power distribution, and clear maintenance procedures. Verify warranty coverage, replacement timelines, firmware support, and remote diagnostics. These details often matter more after deployment.
Do not accept vague compatibility claims.
In my experience, configuration mistakes often start with assuming every 80GB H100 system behaves identically. It does not. A manufacturer may list the correct memory and bandwidth while overlooking storage throughput or network bottlenecks. Test a representative workload before committing. If testing is unavailable, treat that limitation as a risk and negotiate stronger documentation, service terms, and acceptance criteria.
Compare Manufacturer Platforms by GPU Form Factor, PCIe, SXM, and NVLink Support
Choosing an H100 server manufacturer starts with the GPU form factor. SXM systems typically support 700-watt accelerators and higher-density NVLink fabrics. PCIe cards usually operate near 350 watts and fit more conventional server designs. The official H100 technical brief lists up to 900 GB/s of fourth-generation NVLink bandwidth for SXM configurations. That difference affects training speed, cooling, and rack planning.
PCIe platforms offer broader compatibility with standard CPU systems, expansion cards, and existing data-center tools. PCIe 5.0 x16 provides about 128 GB/s of aggregate theoretical bandwidth, but real application performance depends on topology and NUMA placement. A manufacturer should show the complete wiring diagram, not only the GPU count. MLPerf Training v4.1 results also demonstrate that scaling depends heavily on interconnect design, software maturity, and workload tuning, rather than silicon alone.
Power delivery deserves careful inspection. Uptime Institute’s 2024 Global Data Center Survey reports continuing growth in high-density rack deployments, increasing pressure on cooling and facility capacity. Ask whether the platform supports direct liquid cooling, redundant power shelves, and sustained thermal operation. A cheaper PCIe server may be the wiser choice for inference or mixed workloads. For tightly coupled multi-GPU training, SXM and NVLink usually deserve priority. Still, specifications can mislead. I would request a customer workload test before signing, because peak bandwidth rarely equals daily performance.
How to Choose an H100 Server Manufacturer? - Compare Manufacturer Platforms by GPU Form Factor, PCIe, SXM, and NVLink Support
Reference comparison of common H100 server platform configurations. Actual availability, cooling design, firmware features, and supported GPU counts may vary by system manufacturer.
| Platform Profile |
GPU Form Factor |
Typical GPU Count |
Host Interface |
GPU Memory Configuration |
GPU Memory Bandwidth |
NVLink Support |
Best-Fit Workloads |
| Compact PCIe Compute Node |
H100 PCIe add-in card |
1–2 GPUs |
PCIe Gen5 x16 per GPU |
80 GB HBM2e per GPU |
Up to 2.0 TB/s per GPU |
Usually unavailable at system level |
Inference, development, visualization, and smaller distributed jobs |
| Dual-GPU PCIe Server |
H100 PCIe add-in card |
2 GPUs |
PCIe Gen5 x16 per GPU |
80 GB HBM2e per GPU |
Up to 2.0 TB/s per GPU |
Depends on chassis and bridge topology |
Mixed AI and HPC workloads with moderate GPU-to-GPU communication |
| Four-GPU PCIe Server |
H100 PCIe add-in card |
4 GPUs |
PCIe Gen5 x16 per GPU |
80 GB HBM2e per GPU |
Up to 2.0 TB/s per GPU |
Typically PCIe peer-to-peer only |
Batch inference, parameter-efficient fine-tuning, and general-purpose acceleration |
| Eight-GPU PCIe Expansion Server |
H100 PCIe add-in card |
8 GPUs |
PCIe Gen5 x16 per GPU |
80 GB HBM2e per GPU |
Up to 2.0 TB/s per GPU |
No integrated all-to-all NVLink fabric |
Highly parallel jobs that can scale efficiently over PCIe and networking |
| Four-GPU SXM Node |
H100 SXM module |
4 GPUs |
Integrated baseboard connection |
80 GB HBM3 per GPU |
Up to 3.35 TB/s per GPU |
NVLink 4.0; up to 900 GB/s per GPU |
Large-model training and HPC applications with intensive GPU communication |
| Eight-GPU SXM Training Platform |
H100 SXM module |
8 GPUs |
Integrated baseboard connection |
80 GB HBM3 per GPU |
Up to 3.35 TB/s per GPU |
NVLink 4.0 with NVSwitch fabric |
Distributed training, large language models, recommendation systems, and simulation |
| Eight-GPU SXM High-Bandwidth Platform |
H100 SXM module |
8 GPUs |
Integrated baseboard connection |
80 GB HBM3 per GPU |
Up to 3.35 TB/s per GPU |
NVLink 4.0; 900 GB/s GPU-to-GPU bandwidth |
Communication-heavy model training requiring tightly coupled GPU memory access |
| Hybrid PCIe and SXM Cluster Node |
Mixed PCIe cards and SXM modules |
Configuration-dependent |
PCIe Gen5 plus integrated SXM fabric |
Varies by installed GPU type |
Up to 2.0 TB/s PCIe GPU memory bandwidth or 3.35 TB/s SXM bandwidth |
NVLink applies only to supported SXM groups |
Specialized deployments requiring flexible expansion and selected high-bandwidth GPU groups |
Selection guidance: Choose a PCIe platform for deployment flexibility, lower power density, and broad server compatibility. Choose an SXM platform when the application depends on high GPU memory bandwidth, dense GPU packaging, and NVLink or NVSwitch communication. H100 SXM systems commonly use approximately 700 W per GPU, while H100 PCIe cards commonly use approximately 350 W per GPU; rack power and liquid or high-capacity air cooling should be verified before purchase.
Evaluate Performance Claims Using H100 FP8 3,958 TFLOPS and 900GB/s NVLink
When an H100 server manufacturer advertises 3,958 FP8 TFLOPS, ask whether sparsity is enabled. This figure typically reflects structured sparsity, not ordinary dense inference. That distinction changes purchasing decisions. Request the test model, batch size, precision mode, and software versions. Then reproduce the run on identical hardware. Record tokens per second, latency, power draw, and GPU temperature. A peak number alone is weak evidence. Real workloads often use uneven batches, longer context, or mixed precision. Small details matter.
Check the claimed 900GB/s NVLink figure with equal care. Ask whether it describes bidirectional aggregate bandwidth or one-way throughput. Confirm the number of GPUs, link topology, and whether traffic crosses switches. During testing, use a communication benchmark and a representative multi-GPU model. Watch for degraded links, throttling, and CPU or network bottlenecks. A reliable manufacturer should provide logs, cooling specifications, firmware versions, and test conditions. I have seen impressive results weaken when airflow changes or software becomes outdated. That is an uncomfortable limitation, but it deserves attention. Leave room for error. Compare sustained performance over hours, not a brief launch burst.
Audit Cooling, Power, and Rack Design for Multi-GPU H100 Deployment
How to Choose an H100 Server Manufacturer?
Choosing an H100 server manufacturer requires more than comparing GPU counts. Multi-GPU systems create concentrated heat, heavy power demand, and difficult service constraints. Ask for measured thermal data at sustained workload, not only peak specifications. Numbers can deceive. Confirm inlet temperatures, fan curves, coolant flow, and throttling behavior inside a fully populated rack. If liquid cooling is offered, inspect the coolant distribution unit, quick-disconnect quality, leak detection, and maintenance procedure. A small fitting failure can stop an entire cluster.
Power design deserves the same scrutiny. Request a configuration-specific power budget for GPUs, CPUs, memory, storage, and networking. Check PDU ratings, circuit balance, inrush current, grounding, and redundancy under failure conditions. The manufacturer should explain how the system behaves when one power feed disappears. Test reports should identify instruments, workload duration, and ambient temperature. Vague charts are weak evidence.
Rack design often exposes hidden costs. Verify cabinet depth, total weight, rail compatibility, cable paths, airflow direction, and service clearance. Leave room for technicians to replace a GPU without removing neighboring equipment. Confirm liquid pipes, power cables, and network trunks will not block access. During one review, I focused too heavily on cooling capacity and overlooked rear-door clearance. That mistake changed the installation plan. A reliable supplier welcomes site surveys, witnessed acceptance tests, firmware records, and clear replacement procedures. Ask difficult questions before the hardware arrives.
Verify Supply, NVIDIA Certification, Warranty, Security, and Lifecycle Support
How to Choose an H100 Server Manufacturer?
A reliable H100 server manufacturer should prove supply before requesting payment. Ask for current inventory, delivery dates, and the exact accelerator configuration. Request serial-number records, factory photos, and a live video showing the server booting. A polished datasheet is not proof. Confirm memory capacity, cooling design, power requirements, and rack dimensions. Small omissions can create expensive installation delays.
Verify that the system carries valid certification for the H100 platform and supports approved drivers, firmware, and tested operating systems. The warranty should state response times, replacement procedures, onsite options, and coverage for accelerators, power supplies, and cooling parts. Security also deserves direct questions. Check secure boot, firmware controls, access logging, component traceability, and data-erasure procedures after repair. Avoid vague promises. They are difficult to enforce.
Tips: Ask for a sample acceptance checklist before signing. Include burn-in testing, GPU health reports, thermal readings, and network performance. Confirm whether the supplier stocks spare parts locally. Lifecycle support should cover firmware updates, technical escalation, and future repairability. In practice, support quality can vary after delivery. That is easy to underestimate. A manufacturer may appear highly capable during sales, yet respond slowly when a fan fails at midnight. Request references from comparable deployments, but examine them critically. One successful installation does not prove consistent service.
FAQS
SXM systems support higher-power accelerators and dense GPU interconnects. PCIe systems fit standard server designs more easily. PCIe is often practical for inference and mixed workloads.
Choose SXM for tightly coupled, multi-GPU training. It can provide up to 900 GB/s of fourth-generation NVLink bandwidth. Cooling and rack power require careful planning.
PCIe works well with standard CPUs, expansion cards, and existing data-center tools. A lower-power design may suit inference better. That is not always obvious.
GPU count alone says little about performance. The diagram should show PCIe paths, switches, CPU sockets, and NUMA placement. Poor topology can create hidden bottlenecks.
Ask whether structured sparsity is enabled. Request the model, batch size, precision mode, and software versions. Then repeat the test on identical hardware.
Record tokens per second, latency, power draw, and GPU temperature. Test uneven batches and longer context lengths. Peak numbers mislead.
Confirm whether the figure means one-way or bidirectional aggregate bandwidth. Check GPU count, link topology, and switch traffic. Run communication benchmarks with a real multi-GPU model.
Ask about direct liquid cooling, redundant power shelves, and sustained thermal operation. High-density racks can exceed facility limits. Cooling failures are expensive.
Measure sustained performance over several hours, not a brief launch burst. Watch for throttling, degraded links, and CPU bottlenecks. Leave room for error.
Request logs, firmware versions, cooling specifications, and complete test conditions. Customer workload testing is valuable before signing. I would still question impressive results.
Conclusion
Choosing the right h100 server manufacturer requires more than comparing prices or advertised GPU counts. Begin by defining your workload and verifying essential specifications, including 80GB HBM3 memory, 3.35TB/s bandwidth, and a 700W TDP per accelerator. Then compare platforms based on GPU form factor, PCIe or SXM compatibility, and NVLink support. Performance claims should be checked against measurable benchmarks, such as H100 FP8 performance of up to 3,958 TFLOPS and interconnect speeds reaching 900GB/s, while considering how these results apply to your applications.
For multi-GPU deployments, carefully audit cooling capacity, power delivery, airflow, rack density, and serviceability to ensure stable operation. Finally, confirm product availability, certification status, warranty terms, security practices, firmware management, spare-part access, and long-term lifecycle support. A reliable manufacturer should provide transparent documentation, realistic performance data, and a deployment plan that supports both current workloads and future expansion.
 Arkon Server