Choosing a machine learning server manufacturer in 2026 requires more than comparing processor names or advertised GPU counts. A serious decision begins with the workload. Image training, large language models, recommendation systems, and real-time inference create different demands for memory, networking, cooling, and storage. A server that performs well in a benchmark may struggle inside a crowded rack with limited power capacity.
Jensen Huang, NVIDIA’s founder and CEO, has described AI as “the most powerful technology force of our time.” His statement reflects a practical reality: infrastructure choices now influence research speed, operating costs, and business resilience. Therefore, buyers should examine GPU compatibility, accelerator availability, PCIe or NVLink design, CPU balance, and high-speed interconnects. Warranty response matters, too. A delayed replacement can leave an expensive training cluster idle for days.
Look closely at the details.
Ask manufacturers for measured performance under realistic workloads, not only peak specifications. Request power consumption at sustained utilization, thermal limits, firmware policies, and support coverage in your region. Also check whether the manufacturer can provide validated software stacks, driver updates, and expansion paths for future accelerators. These details often reveal more than polished product pages.
There is no perfect choice. A lower-priced system may bring higher integration effort. A premium platform may exceed your actual needs. I have seen teams overbuy GPU capacity while underestimating networking and cooling requirements. That mistake is easy to repeat. This guide evaluates machine learning server manufacturer options through performance, reliability, service quality, scalability, and total cost of ownership. The goal is a defensible decision, not a fashionable one.
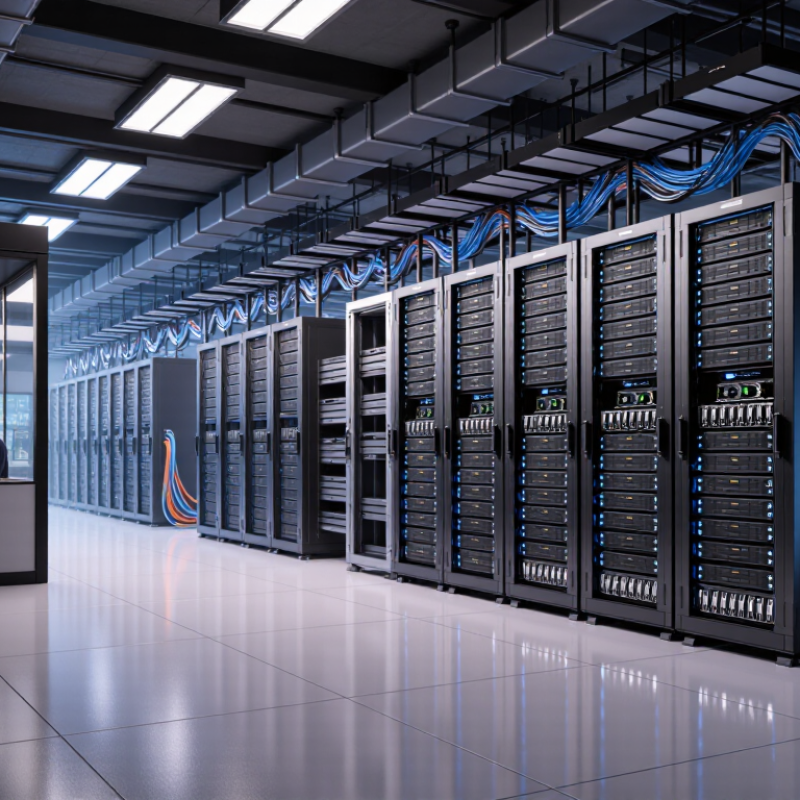
In 2026, a machine learning server is more than a powerful box. It is the operational foundation for training, fine-tuning, testing, and serving models. A reliable server combines accelerators, high-speed memory, fast storage, strong networking, and efficient cooling. It must also support monitoring and secure data handling. Stanford University’s AI Index 2025 reported that AI hardware costs and model-training requirements remain significant barriers for many organizations. Therefore, manufacturers should be judged by complete system performance, not processor speed alone.
The server’s role changes across the machine learning lifecycle. Training needs dense computing and rapid data movement. Inference needs predictable response times and stable energy use. The International Energy Agency reported that data centers consumed about 415 terawatt-hours of electricity in 2024. This makes power efficiency a practical selection issue, not a marketing detail. I have seen teams overbuy computing capacity, then struggle with cooling and software compatibility. That mistake is common. It also deserves honest review.
Tips: Ask manufacturers for measured performance under your workload. Request power data, thermal limits, upgrade paths, and failure-recovery procedures. Check support response times and firmware policies. Use independent benchmarks, such as MLPerf results, but treat them carefully. Benchmark conditions may not match your real data or model. A short pilot can reveal more than a polished brochure. Industry experience still matters.
How to Choose a Machine Learning Server Manufacturer 2026
Choosing a machine learning server manufacturer starts with the workload, not the logo. Define whether you train large models, run inference, or process images continuously. Each use case demands different CPU, accelerator, memory, and storage decisions. A language model may need several high-memory accelerators, while tabular forecasting may depend more on CPU capacity. Measure real data sizes, batch lengths, and response targets. Guesswork becomes expensive quickly.
Hardware details deserve practical inspection. Check accelerator memory before counting processing speed. Confirm the server supports enough memory channels, fast storage lanes, and suitable network bandwidth. Heat and power draw matter in a crowded rack. During testing, record training time, utilization, temperatures, and failure events. My early estimates often ignored data movement, and the resulting bottleneck was surprisingly ordinary: slow storage. Small details matter.
Scalability should be tested before purchase. Ask whether the design allows additional accelerators, memory, drives, or network cards. Review firmware controls, remote monitoring, service procedures, and replacement timelines. A reliable manufacturer should provide clear documentation and measurable support commitments. Run a pilot with your own workload, not only a public benchmark. Leave capacity for growth, but avoid paying for expansion you cannot justify. Plans change. A careful review should change with them.
Choosing a machine learning server manufacturer in 2026 requires more than comparing processor speed. Performance should reflect complete workloads, not attractive component lists. MLPerf Training benchmarks measure time-to-train across standardized tasks, making them useful for comparing accelerator systems. The Stanford AI Index 2024 reports that AI training compute has doubled approximately every 3.4 months since 2010. That pace makes upgrade paths, memory capacity, and interconnect bandwidth practical buying concerns. A fast server can still disappoint.
Reliability needs measurable evidence. Uptime Institute’s Global Data Center Survey 2024 found that more than half of respondents experienced an outage during the previous three years. Ask manufacturers for failure-rate data, thermal testing methods, power-protection design, and replacement procedures. Request references from installations running similar models and workloads. Support quality matters just as much. Check guaranteed response times, spare-parts locations, firmware update policies, and whether engineers understand distributed training. A polished service promise may hide slow escalation.
Tips: Build a weighted scorecard before requesting quotations. Give performance 40%, reliability 30%, and support 30%, then adjust it for your risk profile. Test one real training job with your dataset. Measure training time, GPU utilization, network errors, noise, and energy use. Keep the test imperfect; production behavior rarely matches a showroom benchmark. Also ask what happens during a weekend failure. If the answer is vague, treat that uncertainty as a cost.
Choosing a machine learning server manufacturer requires more than comparing processor speed. Security should be examined at every layer. Ask how firmware updates are signed, tested, and documented. Request evidence of access controls, audit logs, and vulnerability response times. A locked server room still needs secure remote management. I once focused too heavily on encryption and overlooked administrator access records. That mistake changed my evaluation checklist.
Compatibility affects daily productivity. Confirm support for your operating system, accelerators, storage interfaces, and orchestration tools. Test the intended workload before signing a purchase agreement. A server may run a small model well but struggle with larger training jobs. Energy use also deserves measurement, not assumptions. Compare performance per watt during training, cooling requirements, and idle consumption. High peak performance can hide expensive electricity use. Check serviceability, warranty terms, replacement timelines, and upgrade paths. These details shape total cost of ownership.
Tips: Request a live demonstration with your workload. Review three years of energy and maintenance estimates. Ask whether replacement parts remain available after warranty expiry. Treat impressive specifications carefully. Independent testing is useful, but it may not match your data patterns. Document every assumption, including staffing time, software licenses, and downtime risks.
When choosing a machine learning server manufacturer in 2026, verify performance claims through documented testing. Request GPU stress-test logs, thermal readings, memory diagnostics, and power-consumption results under sustained workloads. A short benchmark is not enough. It can hide throttling after several hours.
Check whether the supplier follows recognized quality and security systems, such as ISO 9001 and ISO/IEC 27001. Ask for certificate numbers, issuing bodies, scope, and expiration dates. Testing should also cover firmware updates, cooling failure alerts, redundant power, and component compatibility. Gartner forecast worldwide artificial intelligence spending at 235 billion dollars in 2024, showing why infrastructure reliability deserves serious scrutiny. However, forecast figures do not guarantee your workload will scale smoothly.
Service terms reveal practical supplier experience. Uptime Institute’s 2024 Annual Outage Analysis reported that 54% of respondents said their latest outage cost more than 100,000 dollars, while one in five exceeded one million dollars. Require written response times, replacement-part availability, remote diagnosis procedures, and clear RMA conditions. Confirm who pays shipping and whether labor remains covered after upgrades. Speak with recent customers, not only listed references. I have found that vague wording often matters more than impressive benchmark scores. A careful buyer should record every promise. Some suppliers may still change delivery dates, and that risk should be priced into the purchase.
Define whether you train models, run inference, or process images continuously. Measure data size, batch length, and response targets. Do not rely on guesses.
Check accelerator memory before comparing processing speed. Confirm memory channels, storage lanes, and network bandwidth. Slow storage can become the main bottleneck.
Larger models and batches may require substantial accelerator memory. Insufficient memory can force smaller batches or slower data movement. Speed alone misleads.
Run a pilot using your own dataset and training workload. Record training time, accelerator utilization, network errors, temperatures, and energy use. Public benchmarks are useful, but incomplete.
Check whether you can add accelerators, memory, drives, or network cards. Review available rack space and power capacity. Growth plans often change.
Request thermal testing methods, failure-rate data, power-protection details, and replacement procedures. Ask for references from similar installations. A polished promise proves little.
Check guaranteed response times, spare-parts locations, firmware policies, and escalation procedures. Confirm whether support engineers understand distributed training. Weekend failures reveal reality.
Build a weighted scorecard before requesting quotations. Consider performance, reliability, and support using percentages suited to your risks. Keep the test imperfect; production rarely matches showroom results.
Choosing the right machine learning server manufacturer in 2026 requires more than comparing processor speed or storage capacity. First, define the server’s role, such as model training, inference, data processing, or mixed workloads. Then evaluate computing requirements, including accelerator support, memory, networking, storage, cooling, and future scalability. A suitable solution should deliver consistent performance while remaining flexible as datasets and model complexity grow.
When comparing manufacturers, assess reliability, technical support, warranty coverage, and service response times alongside benchmark results. Security features, software and hardware compatibility, energy efficiency, and total cost of ownership should also influence the decision. Before making a purchase, verify suppliers through demonstrations, workload testing, relevant certifications, reference checks, and clearly documented service terms. This structured approach helps organizations select a dependable server platform that supports long-term machine learning development while balancing performance, operational stability, sustainability, and budget requirements.
Arkon Server