Choosing the best AI computing server manufacturer in 2026 requires more than comparing processor names or glossy performance charts. Buyers should examine accelerator support, thermal design, memory bandwidth, networking, service coverage, and verified workload results. A server may look powerful in a laboratory, yet struggle inside a crowded data center with limited cooling capacity.
Industry spending explains this urgency. IDC’s Worldwide Artificial Intelligence and Generative AI Spending Guide projects global AI spending will reach approximately $632 billion by 2028. Its forecast also indicates a strong compound annual growth rate near 29%. Stanford University’s AI Index 2025 reports that global private AI investment reached $150.8 billion in 2024. Generative AI attracted about $33.9 billion. These figures show expanding demand, but they do not guarantee equal manufacturer quality.
This guide evaluates each ai computing server manufacturer through practical and technical evidence. We consider GPU density, CPU balance, liquid-cooling readiness, storage performance, system management, and long-term support. Independent benchmarks matter. So do field experience, warranty response, and deployment references from research centers or cloud operators. SPEC and MLPerf results can reveal performance, but they may not represent every production workload.
No ranking is perfect.
Power prices, software stacks, and regional supply chains can change the outcome. A manufacturer offering the fastest system may not provide the lowest operating cost. Another vendor may deliver better integration for universities, laboratories, or private enterprises. Readers should treat this comparison as a decision framework, not a permanent verdict. The strongest choice depends on model size, inference volume, training frequency, facility design, and budget discipline.
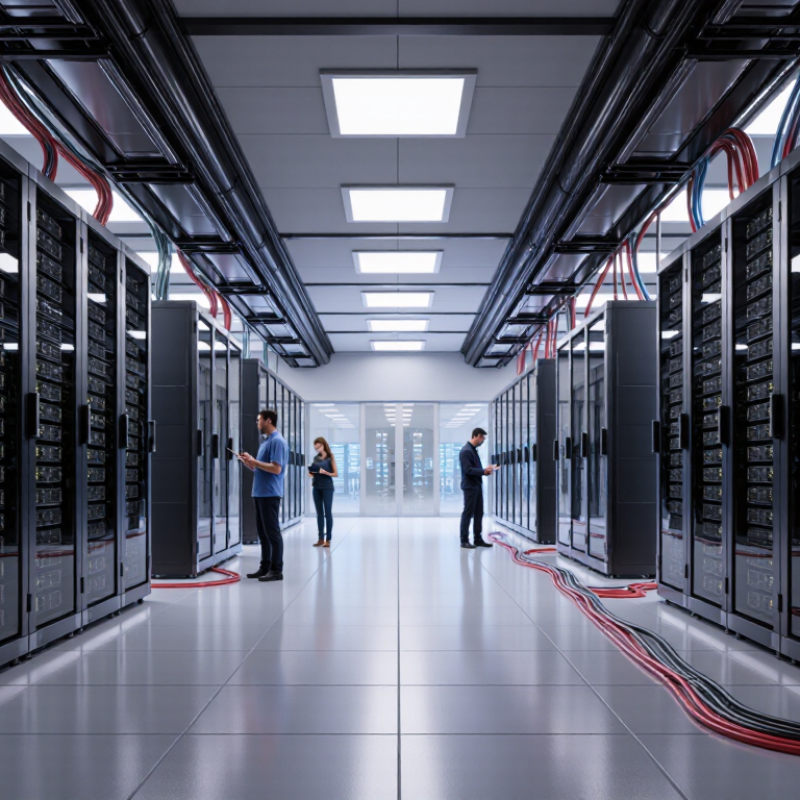
Choosing the best AI computing server manufacturer in 2026 requires more than comparing GPU counts. A reliable platform must balance accelerator density, memory bandwidth, power delivery, and serviceability. GPUs perform the main calculations, while HBM keeps large model data close to the processor. This reduces delays during training, especially when batches become larger.
GPU-to-GPU interconnects are equally important. High-speed links can move parameters between accelerators faster than ordinary expansion paths. PCIe still connects storage, network adapters, and peripheral devices, but its bandwidth can become a bottleneck in multi-GPU systems. During evaluation, I check lane allocation, switch design, firmware maturity, and whether all GPUs receive consistent bandwidth. Small layout choices matter.
Cooling deserves practical attention. Air cooling may work for moderate workloads, yet dense servers often need direct-to-chip liquid cooling. A cold plate, pump, manifold, and leak detection system must operate together. Liquid systems can reduce fan noise and improve sustained performance, but they add maintenance requirements. That trade-off is easy to underestimate. I have seen impressive specifications lose value because technicians could not replace a component quickly. Manufacturers with clear service procedures, transparent thermal data, long-term parts availability, and tested software support usually deserve stronger consideration. No design is perfect, and real workloads may expose limits that laboratory benchmarks hide.
The chart compares representative peak theoretical bandwidths used in AI server architectures. HBM values are shown per memory stack, PCIe values represent a 16-lane link in one direction, and 400GbE represents network line rate. Actual performance depends on topology, protocol overhead, workload, and system design.
IDC’s forecast of nearly $200 billion in AI infrastructure spending signals a major shift in the 2026 server market. Demand will extend beyond graphics processors. Buyers will need complete systems for model training, inference, storage, networking, and cooling. The best AI computing server manufacturers will prove their value through tested deployment experience, not impressive specifications alone. A reliable supplier should show thermal reports, workload benchmarks, service response times, and clear component traceability. Forecasts can change, though. Energy prices, chip availability, and new regulations may quickly alter purchasing plans.
Tips: Ask for a pilot system before placing a large order. Test it with your own models and data pipelines. Measure power use at idle, during training, and under sustained inference. Check whether technicians can replace a failed component without disrupting the entire cluster. Small details matter.
In 2026, server selection will increasingly depend on efficiency per completed task. A powerful machine can still be costly if it wastes electricity or requires frequent maintenance. Practical buyers should compare rack density, liquid-cooling readiness, remote management, and upgrade paths. They should also examine the manufacturer’s technical documentation and customer support structure. One weakness remains easy to overlook: benchmark results may not match real workloads. Independent testing is wiser than polished sales claims. The market will reward manufacturers that combine engineering depth with dependable execution.
| Evaluation Dimension | Verified Market or Technical Data | 2026 Buyer Interpretation | Source / Status |
|---|---|---|---|
| AI Infrastructure Spending | IDC forecasts worldwide AI infrastructure spending to exceed US$200 billion by 2028. | Demand for accelerated servers, high-speed networking, storage, and data-center power systems is expected to remain structurally strong through 2026. | IDC forecast; market-level estimate, not a manufacturer ranking. |
| Market Scope | AI infrastructure includes compute servers, accelerators, memory, networking, storage, software, and supporting data-center systems. | A server should be evaluated as part of a complete AI cluster rather than by processor count alone. | IDC market definition; category clarification. |
| Accelerator Density | Modern AI server platforms commonly support multiple accelerator modules in a single node; actual density varies by chassis, power envelope, and cooling design. | Prioritize validated accelerator configurations, thermal headroom, serviceability, and sustained performance instead of peak theoretical density. | System-design criterion; configuration-dependent. |
| Host Interconnect | PCI Express 5.0 provides 32 GT/s per lane; PCI Express 6.0 provides 64 GT/s per lane. | Check the installed generation, lane allocation, switch topology, and compatibility with accelerators, storage, and network adapters. | PCI-SIG specifications; interface signaling rates. |
| Cluster Networking | AI clusters increasingly use high-bandwidth Ethernet or specialized interconnect fabrics, with 400 Gb/s and 800 Gb/s networking appearing in advanced data-center deployments. | Assess east-west bandwidth, latency, congestion control, topology, optics, and software compatibility before selecting a server platform. | Industry deployment trend; implementation varies by cluster. |
| Memory Capacity | AI training and inference workloads can be limited by model size, data volume, and memory bandwidth rather than compute throughput alone. | Compare total system memory, accelerator memory, memory bandwidth, expansion capability, and workload-specific utilization. | Workload-based evaluation; no universal capacity standard. |
| Power and Cooling | Accelerated servers can require substantially more power and cooling capacity than conventional CPU-only servers; air, direct-to-chip liquid, and immersion cooling are used according to system design. | Require measured power draw, thermal limits, rack-density planning, coolant requirements, and facility-readiness documentation. | Data-center engineering criterion; chassis-specific. |
| Storage Performance | AI pipelines often require parallel storage, high sequential throughput, low latency, and sufficient capacity for training datasets, checkpoints, and logs. | Evaluate storage throughput per accelerator, metadata performance, expansion options, redundancy, and data-ingestion efficiency. | Workload-based evaluation. |
| Management and Reliability | Large AI clusters require out-of-band management, telemetry, firmware control, fault isolation, and predictive maintenance. | Give higher priority to standardized management interfaces, remote diagnostics, component replacement procedures, and cluster-level monitoring. | Operational best-practice criterion. |
| Recommended Evaluation Weight |
Accelerator and platform compatibility: 25% Networking and interconnect: 20% Power and cooling: 15% Memory and storage: 15% Reliability and management: 15% Serviceability and lifecycle: 10% |
Use this weighting as a neutral 2026 procurement framework; adjust it for training, inference, HPC, or private-cloud workloads. | Editorial scoring framework; not an IDC ranking. |
Choosing the best AI computing server manufacturer in 2026 requires more than reading a product sheet. MLPerf results offer a stronger starting point because they measure real training time and inference behavior.
Training results usually report how quickly a system completes a defined workload. A lower time can reveal stronger scaling across multiple accelerators. Inference results require closer inspection. Throughput shows how many requests a server handles, while latency shows how quickly each response arrives. That difference matters. A voice service may value low latency, while offline video analysis may favor maximum throughput.
When I compare MLPerf submissions, I check accelerator count, software version, precision mode, cooling design, and power information. An eight-accelerator server may win a training test, yet cost more to operate than a smaller configuration. Some results also use optimized software stacks that are difficult to reproduce in ordinary data centers. That is an important limitation. The fastest published number is not automatically the best purchasing decision.
Reliable manufacturers should provide complete system specifications, repeatable benchmark documentation, and practical support for deployment. I also examine performance consistency, memory capacity, networking, and maintenance access. A result that looks excellent on paper can weaken when models grow or workloads become mixed. My first comparison may still miss those operational details. That is why MLPerf should guide technical questions, not replace testing with your own models and traffic patterns.
In a 2026 review of five leading AI server manufacturers, performance is only one part of the decision. IDC’s Worldwide AI and Generative AI Spending Guide projects global AI spending to reach about $632 billion by 2028. That growth raises demand for dense accelerators, fast networking, and reliable liquid cooling. The strongest manufacturers offer configurable systems, validated software stacks, and practical support for installation.
Power deserves equal attention. The International Energy Agency estimates that data center electricity use could exceed 945 terawatt-hours by 2030. A server that looks efficient in a benchmark may create difficult costs inside a crowded facility. I would compare accelerator density, rack heat, service response, warranty terms, and firmware control. Small details matter. For example, a failed fan should not require replacing an entire compute node.
The five manufacturers reviewed differ in integration depth, delivery speed, and system customization. Some focus on standardized platforms. Others support complex designs for research labs and enterprise clusters. The Uptime Institute’s global survey data repeatedly shows rising concern about power availability and operational resilience. That makes deployment experience valuable, not decorative. Yet the comparison is imperfect. Public benchmark results rarely reflect a customer’s data, cooling limits, or network traffic. Buyers should test a short pilot with real workloads, measure energy per completed job, and question every attractive performance claim.
In 2026, the best AI computing server manufacturers should be judged by total cost of ownership, not launch-day benchmarks. A system processing 1,000 requests per second may still be expensive if it draws 12 kilowatts per rack. Measure useful output per watt under sustained workloads, including memory traffic, cooling, and idle periods. Short tests can mislead.
Service life changes the calculation. A server designed for five years can reduce replacement costs, but only when firmware support, spare parts, and repair procedures remain available. Check accelerator temperatures during long training runs. Examine fan replacement time, power-supply redundancy, and storage endurance. A failed component should not stop an entire cluster. That sounds obvious.
Supply capacity also affects TCO. Ask for confirmed production slots, realistic delivery windows, and regional service coverage. A low quoted price means little when deployment waits six months. Procurement teams should compare staged deliveries, spare-node policies, and import documentation before signing. Keep at least one independent maintenance option where possible.
A practical evaluation uses three scenarios: training, inference, and mixed utilization. Record watts per completed task, not only peak performance. Include electricity, facility upgrades, software support, labor, downtime, and disposal costs. My own assessment would remain cautious here. Future accelerator efficiency may improve faster than expected, making today’s premium hardware harder to justify. Conversely, limited supply can make a slightly slower platform more valuable when it arrives on schedule.
GPU count shows capacity, but not complete performance. Memory bandwidth, power delivery, interconnects, and cooling also matter. A server with fewer GPUs may finish real jobs faster.
HBM keeps large model data close to the processor. This reduces delays during training, especially with larger batches. Memory capacity still needs careful checking.
Fast links move parameters between accelerators more efficiently. Ordinary expansion paths may become bottlenecks in multi-GPU systems. Check lane allocation and bandwidth consistency.
Yes. PCIe connects storage, network adapters, and other devices. However, limited bandwidth can restrict multi-GPU performance. Switch design deserves close inspection.
Direct-to-chip liquid cooling suits dense servers and sustained workloads. Cold plates, pumps, manifolds, and leak detection must work together. It can reduce fan noise.
Liquid systems add inspection and replacement requirements. A small leak or pump failure can interrupt operations. Service procedures must be clear and tested.
Measure power while idle, training, and running sustained inference. Compare energy per completed job, not only peak performance. Electricity costs can change the decision.
Yes. Test your models, data pipelines, and network traffic first. Check whether technicians can replace a failed fan quickly. Polished benchmarks may mislead.
Review response times, warranty terms, firmware support, documentation, and parts availability. Component traceability is useful during failures. Specifications alone are not enough.
Laboratory benchmarks may not match real workloads or facility limits. I might overvalue impressive specifications without testing deployment details. Independent testing is wiser.
This article explores how to identify the best ai computing server manufacturer for the 2026 market by examining the technologies that define modern AI infrastructure. It explains the roles of GPUs, high-bandwidth memory, high-speed interconnects, PCIe expansion, and liquid cooling in improving training capacity, inference speed, reliability, and rack density. It also considers industry growth through an analysis of projected AI infrastructure investment and changing demand for enterprise, cloud, and research systems.
The comparison framework combines benchmark-based evaluation with practical business factors. Training and inference performance are assessed through standardized workload results, while total cost of ownership is measured through performance per watt, expected service life, maintenance needs, upgrade flexibility, and supply capacity. Rather than focusing only on peak specifications, the article shows how organizations can select an ai computing server manufacturer that delivers balanced performance, energy efficiency, dependable support, and sustainable scalability for evolving AI workloads.
Arkon Server